
Strategic branding for AI and ML companies (beyond the benchmark)
AI and ML brand positioning once the two letters signal nothing: what keeps its value, benchmarks with conditions, and one story for two approvers.
- Every company in every category claims AI now, so the claim itself signals nothing. Positioning that leans on the two letters starts from zero.
- The moat is rarely the model. Weights lose value with every release, while data rights, evaluation suites and distribution keep theirs.
- Two functions approve an AI purchase, and they fear different things. The engineer worries about latency and reliability; the risk owner worries about liability and lock-in.
- A brand built around this quarter's model goes stale at the next release. Build it around whatever is still true after that.
Strategic branding for an AI or machine learning company is the work of deciding what the brand claims once a benchmark has already been posted. A benchmark proves a model. It does not prove a business, and in a category where every competitor claims the same two letters and the same visual language, that gap is where the actual brand decision sits.
Why doesn't calling yourself an AI company mean anything anymore?
Calling yourself an AI company means little because nearly every competitor makes the same claim. Stanford's 2025 AI Index reports that 78% of organisations used AI in 2024, up from 55% the year before. A word nearly everyone uses no longer separates anyone.
Buyers have learned to skip the word and look for the sentence underneath it. That sentence has to say what the company is: model, infrastructure, application or data. It also has to say what makes that hard to copy.
i3systems met this problem directly. Its founder, Dr. Mallesh, first briefed us to put "automation" at the centre, the word every competitor used. The work moved the brand one step to the side of the category, to the tagline "It Gets Simpler."
The visual language has converged as far as the vocabulary. Dark gradients, glowing orbs and the word intelligence appear across most sites in the category. Swap the logos on two of them and few buyers would notice.
Who is an AI company really competing against?
An AI company usually competes against three groups at once, and only two of them show up as named rivals:
- The foundation labs, who set the ceiling on raw capability.
- The open-weight alternatives, who compete on cost and control.
- The customer's own engineering team, weighing whether to build it in-house.
The second group is closer than it looks. The AI Index found that open-weight models cut their gap to closed models from 8% to 1.7% on some benchmarks in a single year.
The third group rarely appears in a sales call. For many applied AI companies, the honest argument is why buying beats building, and that argument is usually missing from the website.
If the model isn't the moat, what is?
The moat is usually whatever keeps its value at the next release. Model weights are perishable, because a better model ships from a well-funded lab on a schedule nobody else controls. The AI Index measured the cost of GPT-3.5-level inference falling more than 280-fold between November 2022 and October 2024.
What tends to survive that cycle:
- Data rights nobody else can license.
- An evaluation suite built up over years.
- Distribution that is already in place.
- A cost structure a smaller competitor cannot match.
- Deep integration with the customer's own systems.
Most AI brands market the part that is losing value, because it is the easiest part to demo. Our AI and machine learning branding starts by finding the part that lasts and building the story around it.
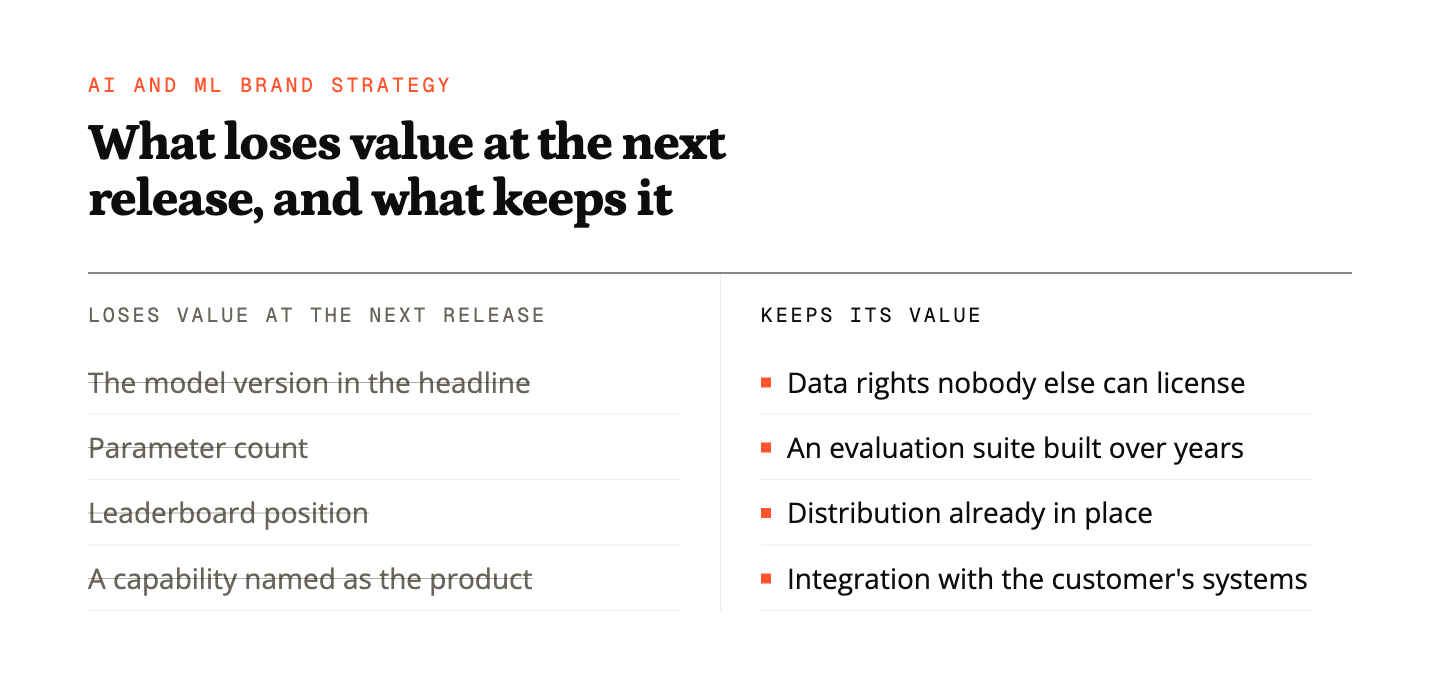
The same logic applies to the brand's own claims. A story anchored to a model version, a parameter count or a leaderboard position is true for one release and false for the next. Anchor it to the data pipeline, the evaluation work and the deployment surface, which are still there after the model has been swapped twice.
Why do buyers distrust the benchmark table?
Buyers distrust the benchmark table because every vendor publishes the evaluation it wins. Shared suites exist, such as MLPerf from MLCommons and Stanford's HELM. Most tables on vendor sites are still self-run, on hardware and settings the vendor chose.
The margins are thin as well. In the AI Index, the gap between the top model and the tenth fell from 11.9% to 5.4% in a year. The top two were separated by 0.7%.
A benchmark earns belief when it carries its conditions:
- The suite, named and linked.
- The hardware and context window.
- The date it was run.
- The tasks where the model loses.
There is a published template for this. Model cards, proposed in 2018, ask for evaluation across a range of conditions and a statement of intended use. The same rule holds for efficacy numbers in cybersecurity.
Cloudphysician, a healthcare AI company, states its numbers on the home page, where a clinician can check them.

Who has to approve an AI purchase, and what does each person fear?
Two functions usually approve an AI purchase, and they fear different things. The engineer integrating the model worries about latency, reliability and whether demo behaviour survives production traffic. The risk owner, in procurement, legal or platform, worries about liability if the model is wrong and lock-in if switching proves hard.
The risk owner now has formal frameworks to check a vendor against. The EU's AI Act sorts AI systems into four levels of risk, with documentation, logging and human oversight required for high-risk systems. In the US, NIST's AI Risk Management Framework gives organisations a voluntary structure for the same questions.
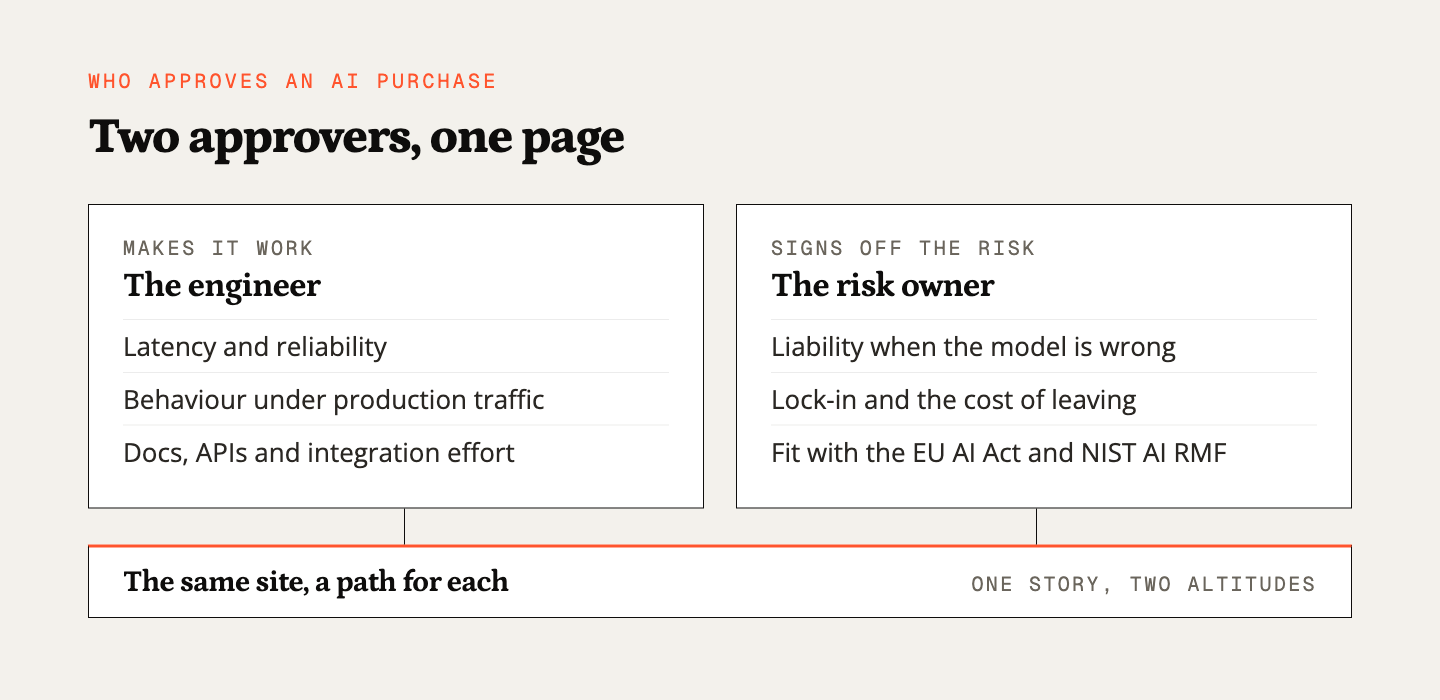
A brand written only for the engineer reads as a spec sheet and never reaches the person signing off the risk. Written only for the risk owner, it reads as a compliance pitch and never convinces the engineer. Each needs a path through the same site, as we describe in writing for investors, buyers and engineers at once.
Should documentation be treated as marketing?
Yes, because for a technical buyer the documentation is where the real evaluation happens. An engineer reads the docs before anything the marketing team wrote. Confusing or incomplete docs are read as a signal about the product.
Most AI companies treat documentation as a footer link, generated and left alone. Designing it with the care given to the landing page is one of the few open advantages in this category.
The same discipline now decides how answer engines describe you. ChatGPT, Claude and Perplexity do the first round of screening for many buyers, and they often misdescribe an AI company's capability. A page that states the model, the task and the evaluation conditions plainly is harder to paraphrase into a different product.
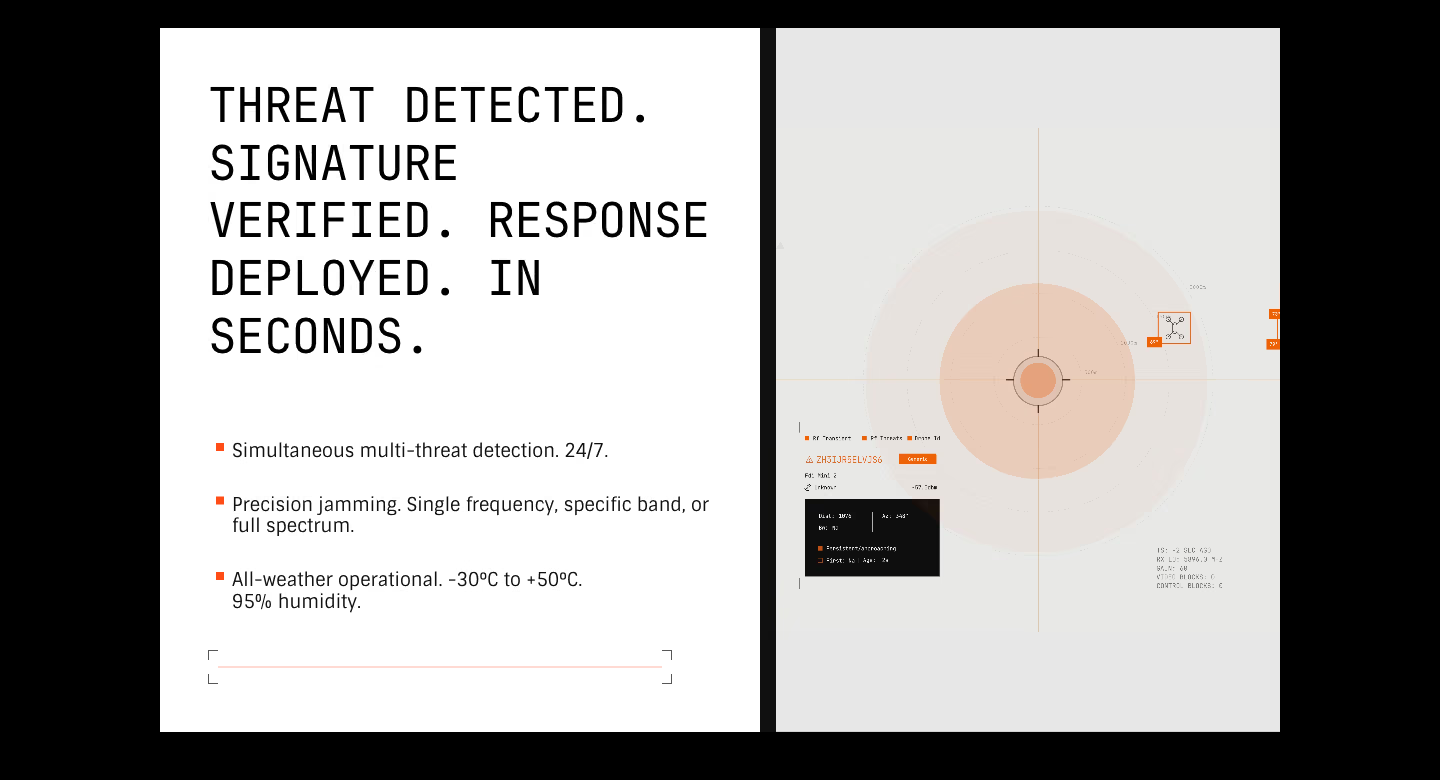
A plain llms.txt file is one proposed way to give those engines a clean summary. Armory, an AI-powered counter-drone company, states its product as a sequence: detection, verification and response. A capability written that way is hard to misread.
What does naming need to survive in this category?
A naming system here needs three layers held together, with room for a generation that does not exist yet:
- The company.
- The model or product family.
- The individual release.
A product named after a single capability becomes a liability once that capability is standard across the category. Vecton shows the company-level version of the problem.
It was called Graphik AI, a name that signalled design work after the company had moved into AI for banks and insurers. The new name came out of an exploration of 200 to 300 options.
Decide the naming architecture before naming the next release. A system built for today's model has no place for the one you ship in eight months, and renaming mid-adoption costs credibility.
What did the H2LooP engagement actually involve?
The H2LooP engagement was a film and motion graphics for a company building system software for AI infrastructure. H2LooP's case study shows that layer underneath the model, which most AI marketing never touches. The film is titled "Why System Software Is AI's Hardest Problem."
We have not published an outcome for that engagement. The case study page shows the work itself, with its scope stated and no outcome claimed.
What does an engagement deliver, and how long does it take?
An engagement takes nine to sixteen weeks from kickoff to a finished brand system, at a fixed scope and one price. The price is quoted after a thirty-minute call, and the ranges are on our pricing page.
The work runs in this order:
- Category and positioning: model, infrastructure, application or data.
- Naming, where the architecture needs it.
- Narrative and identity.
- Messaging for each audience, from the engineer to the risk owner.
- A brand book that records all of it.
The team is nineteen people, ten of them engineers by degree, across strategy, 3D, delivery and build. We sign an NDA before reviewing unpublished architecture, training data or evaluation methods, as set out in branding under NDA.
When is this not a fit?
A refreshed landing page or a single product announcement is not a fit. A freelance designer will do that faster and for less, because it needs no category decision and no naming architecture. If only the site needs work, our AI and ML website service is the narrower option.
Branding also cannot supply a moat that does not exist yet. If nothing about the company survives the model commoditising, that is a product question to answer first. This suits a company that knows what lasts about it and needs that made legible.
FAQ
Everyone claims AI. How do you differentiate us?
By moving the claim off the model. We look for what keeps its value: data rights, evaluation suites, distribution and cost structure. That is usually the real business, and rarely the headline the company started with.
Do you work with applied AI companies or AI infrastructure companies?
Both, and the distinction changes more than most founders expect. It changes your comparables, your margin expectations and which buyer the brand speaks to first. An infrastructure company usually sells to the engineer first, while an applied company often has to win the risk owner just as early.
What is the status of the H2LooP engagement?
The scope was a film and motion graphics, for a company building system software for AI infrastructure. No outcome has been published for that engagement.
Does branding replace a benchmark or an evaluation?
No. Branding cannot prove a model performs. It can make sure the evaluation is presented with its conditions attached, so a sceptical buyer can check it.
When should an AI or machine learning company hire someone else?
When the need is a single page or a quick refresh, or when the company cannot yet say what survives once the model it is built around gets replaced.
Written by Mejo Kuriachan. More in the blog, the glossary and the FAQ.